Discord to Open Public Server Content to Google Search, Igniting Debate Over Discoverability and User Privacy

Discord, the widely popular communication platform, has announced a significant policy shift that will make content from eligible public servers discoverable through Google and other major search engines starting in mid-December 2026. This move, detailed in a recent blog post by the company, aims to transform Discord from a closed "treasure trove" of information into a more accessible resource for the broader internet, but it has simultaneously ignited a vigorous debate among its user base regarding privacy and the nature of online public discourse.
A New Era of Discoverability for Discord Content
For years, vast amounts of valuable information, ranging from intricate gaming guides and troubleshooting tips to niche community discussions and expert advice, have resided within Discord’s servers, largely inaccessible to conventional search engines. Users often expressed frustration when Google searches led them to Reddit threads or forum posts that merely referenced a solution found on a Discord server, requiring them to join a new community to access the information. Discord’s new initiative seeks to address this specific pain point, making these rich reservoirs of knowledge available to anyone searching the web.
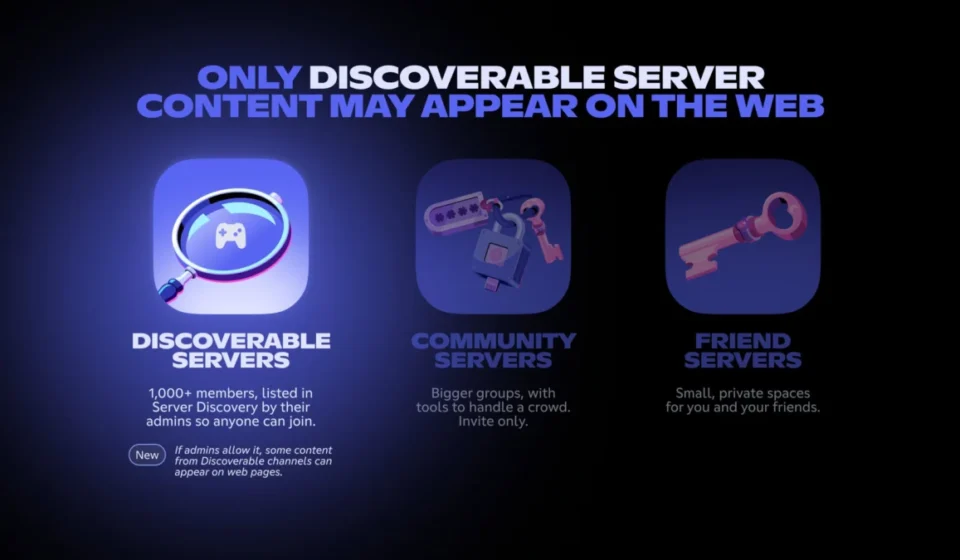
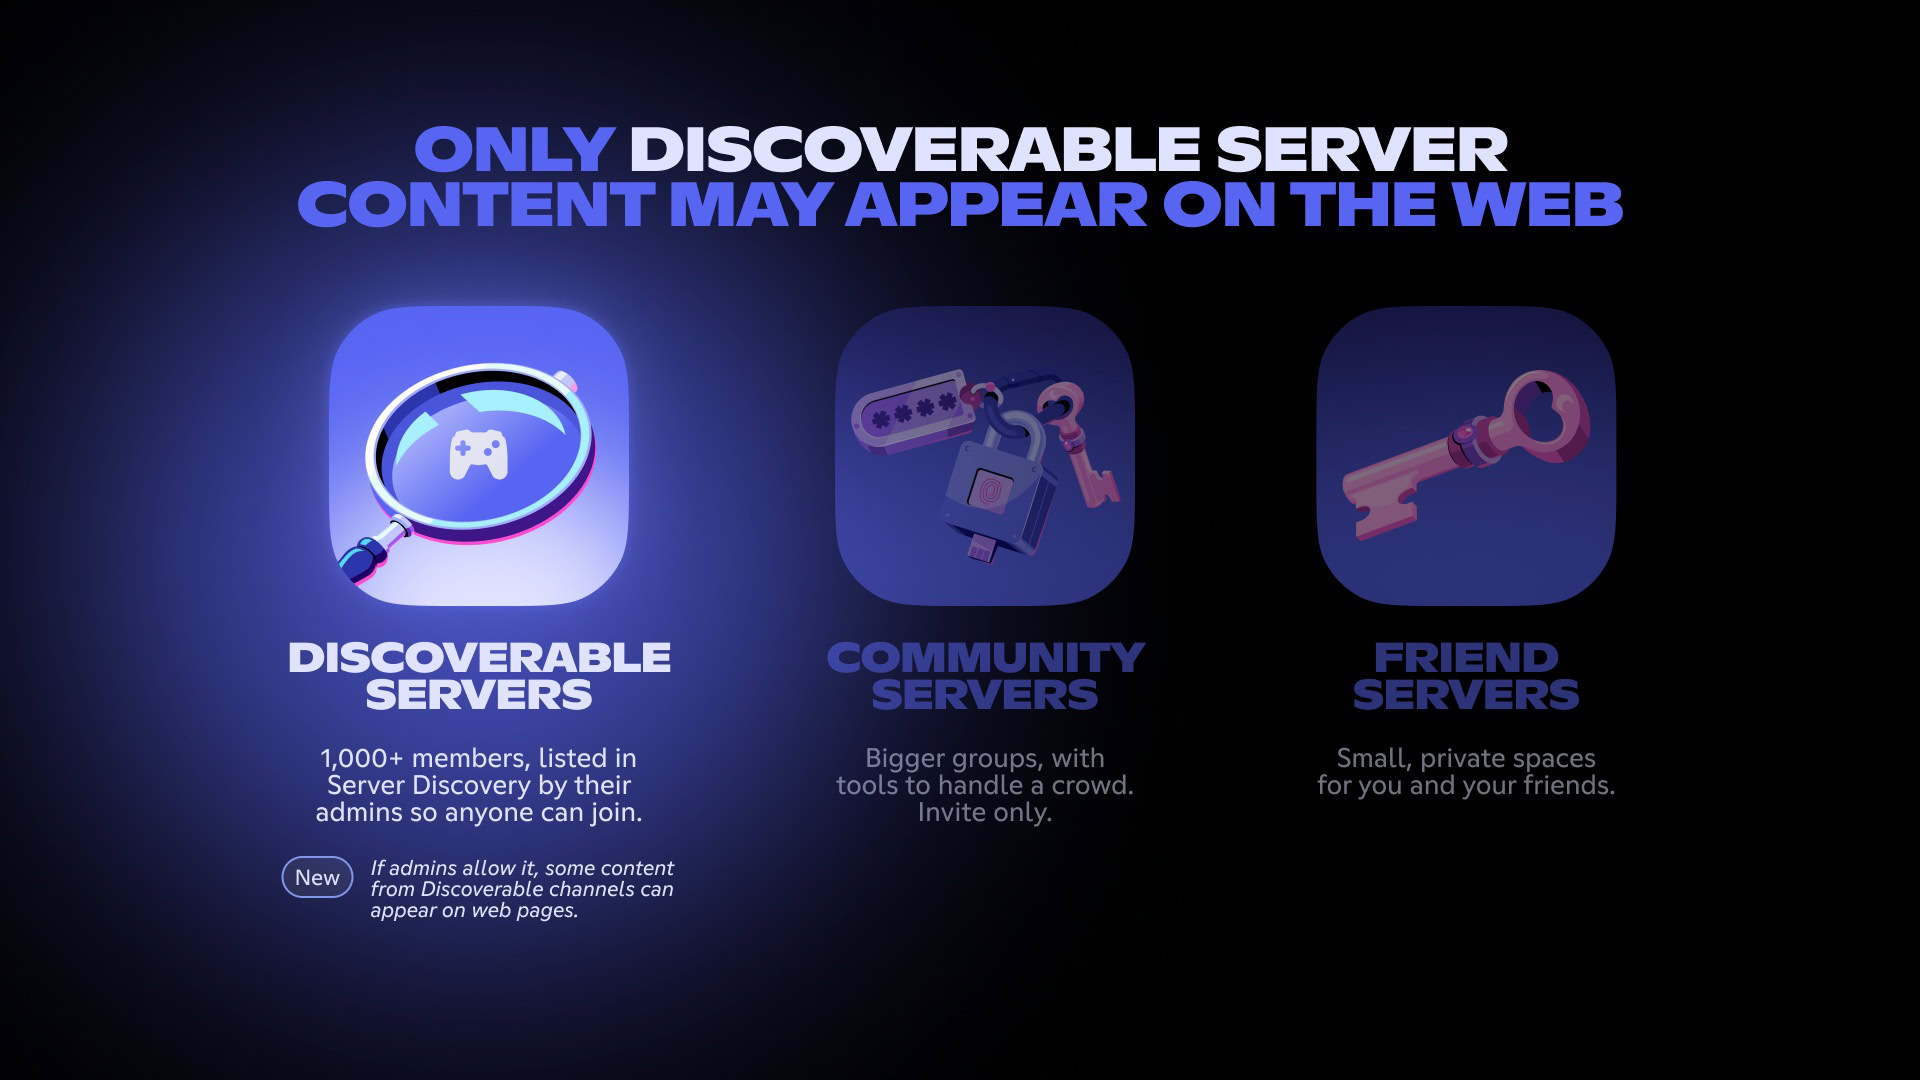
The core of this change targets "Discoverable Servers" – public communities that meet specific criteria: they must have been active for at least eight weeks, boast a minimum of 1,000 members, and be listed in Discord’s official Server Discovery directory. These parameters ensure that the content being indexed originates from established, larger public communities rather than smaller, more private groups.
The rollout is structured in two main phases. Beginning November 16, 2026, each eligible server will gain a public Server Web Page. These pages are designed to include AI-generated summaries of conversations from selected public channels, offering a condensed overview of the discussions taking place within the community. The more significant phase commences in mid-December 2026, when individual messages from participating public channels may begin to appear word-for-word on these dedicated web pages and subsequently in Google search results.
Protecting User Privacy Amidst Expanded Reach
Recognizing the potential privacy implications of such a change, Discord has emphasized that it is implementing robust privacy controls ahead of the full rollout. These controls empower both server administrators and individual users to manage the visibility of their content on the wider web. Crucially, the company has clarified that this initiative will not expose private messages, group direct messages (DMs), private servers, or channels explicitly designated as restricted. Furthermore, to mitigate personal identification risks, published messages will not include usernames or avatars, and importantly, no messages sent prior to the December 2026 rollout will be indexed.
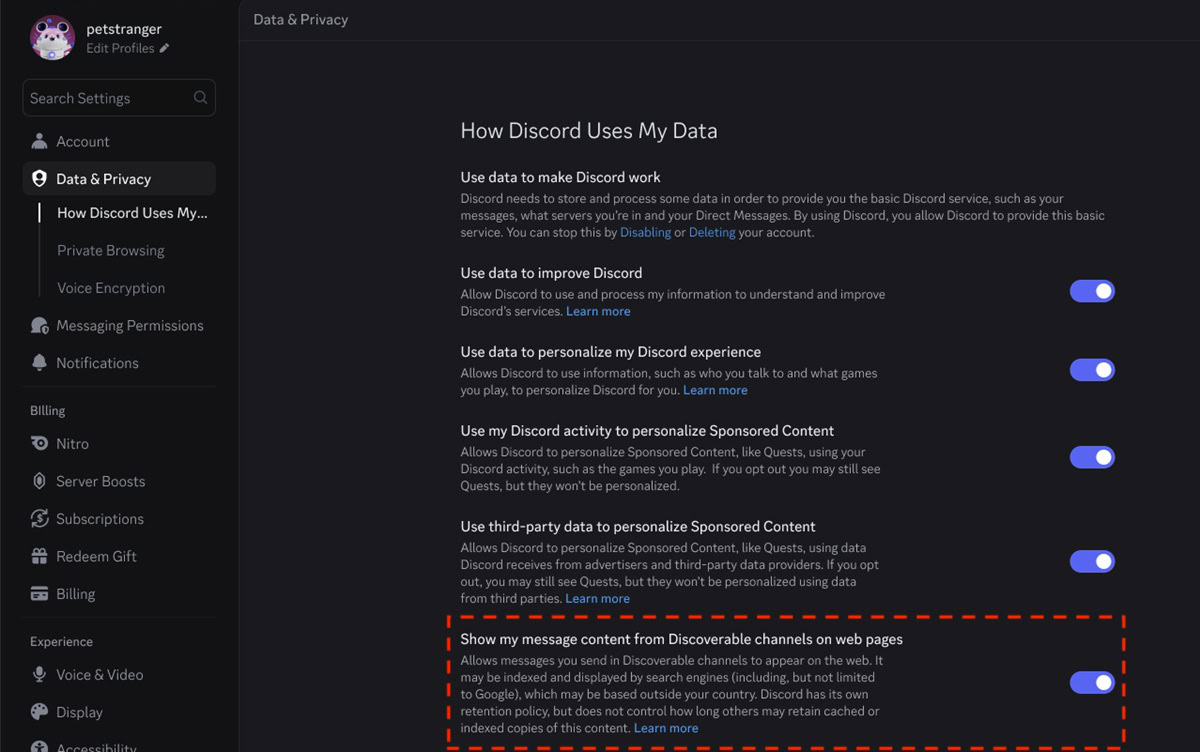
For individual users, Discord has introduced a new privacy switch. This setting, accessible via the web or desktop interface (User Settings > Privacy & Safety), allows users to disable the linking of their public server content to web pages across all Discoverable Servers they are part of. This global opt-out mechanism streamlines the process for users concerned about their contributions becoming publicly searchable. While this control is not yet directly available within the Android or iOS apps, preferences set on desktop or web platforms will seamlessly carry over to mobile devices.
Server administrators are also provided with a comprehensive suite of controls under "Server Settings > Community > Web Presence." From this interface, administrators can choose to turn off "Channel Messages" and "Channel Summaries" entirely for their server, or selectively choose which individual public channels are permitted to contribute content to the web pages and search indexes. These administrative controls are also currently available only through the desktop and web versions of Discord.
A critical point for users to understand is the persistence of data. Opting out of the feature as an individual user or administrator primarily protects messages sent after the setting has been changed. Messages posted while sharing was enabled may still appear online unless they are manually deleted from Discord. Moreover, search engines, once they have indexed content, may retain cached copies even after Discord removes the original content or if a server’s publishing features are later disabled. This highlights the enduring nature of information once it enters the public domain of the internet.
Geographic considerations also play a significant role in the default settings for this feature. In most regions, including the United States, the functionality will be enabled by default for eligible adult users. However, users residing in the European Union (EU)/European Economic Area (EEA), the United Kingdom, Canada, Brazil, Australia, and South Korea will need to explicitly opt-in for their content to be discoverable. Additionally, accounts belonging to teenage users are entirely excluded from this feature, reflecting a heightened focus on protecting younger users’ privacy.
The Evolving Landscape of Online Information and Community
This strategic shift by Discord represents a fascinating intersection of the platform’s evolution, the broader internet’s changing dynamics, and ongoing debates about digital privacy. Discord, which launched in 2015, rapidly grew beyond its initial gaming roots to become a ubiquitous platform for diverse communities. With over 150 million monthly active users and millions of active servers as of recent reports, it has indeed become a significant repository of human knowledge and interaction. Its success, however, also highlighted a growing trend in online communication: the fragmentation of the "open web" into a series of walled gardens or "dark social" platforms where public discussions are not easily discoverable by external search engines.
Historically, the internet thrived on open forums, message boards, and early social networks where public discussions were readily indexed, fostering a collective, searchable knowledge base. Over time, as platforms like Facebook, Twitter (now X), and later Discord gained prominence, much of this public discourse became siloed. While these platforms offered more intimate and controlled environments, they inadvertently created barriers to information access for those outside their immediate communities. Discord’s move can be seen as an attempt to bridge this gap, allowing its content to once again contribute to the collective knowledge accessible via general web searches.
From a user perspective, the benefits of improved discoverability are clear. For someone troubleshooting a specific software bug, researching a niche hobby, or seeking a specific piece of lore from a video game, direct access to relevant Discord discussions via Google could save considerable time and effort. It could also enhance the visibility of smaller, specialized communities, helping them attract new members who might otherwise never find them. For creators and community leaders on Discord, this could translate into increased engagement and growth for their servers, as their valuable content gains a wider audience.
The Privacy Conundrum and User Reactions
Despite the potential benefits, the announcement has been met with considerable apprehension and criticism from a segment of Discord’s user base and privacy advocates. The core concern revolves around the fundamental shift in the perceived "publicness" of a conversation. While a public Discord channel is technically accessible to anyone who joins the server, there’s an implicit understanding among many users that such a conversation is contained within that specific community, not broadcast to the entire internet. The prospect of casual remarks or detailed discussions, even without usernames, appearing in Google search results changes the context and permanence of these interactions.
This "contextual privacy" is a critical aspect. Sharing an opinion or a piece of information within a community of known (or semi-known) individuals, even if it’s a large public one, is qualitatively different from having that content indexed and perpetually available to an anonymous, global audience. Even with the removal of usernames and avatars, context within a message can often be enough to identify individuals or reveal sensitive personal details. The potential for past statements to resurface unexpectedly, leading to doxing, harassment, or misinterpretation outside their original context, is a significant worry.
Another major point of contention is the "default-on" setting for many regions. Critics argue that privacy-focused features should ideally be opt-in, placing the burden on users to actively choose to share their content rather than requiring them to opt-out. Reports from some Reddit users claiming their preference switch was found to be on after previously being disabled, though unverified, further fuel distrust and concern about user agency in managing their data.
Furthermore, the rise of artificial intelligence and large language models (LLMs) adds another layer of complexity. Making vast amounts of conversational data publicly accessible inevitably makes it available for scraping and use in training AI models. This raises ethical questions about data ownership, consent, and the potential for commercially valuable content to be consumed without compensation or explicit permission from its original creators. While Discord’s blog post highlights AI-generated summaries on server web pages, the broader implication of public content being used for other AI training purposes is a significant concern for many.
Broader Implications and the Future of Online Discourse
Discord’s decision reflects a broader industry trend where platforms grapple with the balance between fostering vibrant, closed communities and contributing to the wider, searchable web. For platforms like Discord, making content discoverable could be a strategic move to enhance its utility, attract new users, and potentially open new avenues for monetization, perhaps through more sophisticated search functionalities or data licensing agreements in the future.
For Google, indexing more of Discord’s content aligns with its mission to organize the world’s information and make it universally accessible. As more of human interaction moves to closed platforms, Google faces the challenge of maintaining its comprehensiveness as a search engine. This partnership, therefore, serves both companies’ strategic interests.
Ultimately, Discord’s move is a double-edged sword. It addresses a genuine need for better information discoverability on the internet, potentially revitalizing the concept of a truly "open web" where valuable discussions are not locked away. However, it does so at the cost of unsettling traditional notions of privacy within online communities. The success of this initiative, and its long-term impact on Discord’s user base, will hinge on how effectively the platform can manage user concerns, uphold its privacy commitments, and foster a transparent environment where users feel truly in control of their digital footprint. As the mid-December 2026 deadline approaches, the debate over discoverability versus digital privacy is only set to intensify.